正在加载页面…
从发现、理解到交流,让研究的每一步更进一步。
近期优质论文精选,帮你更快找到值得深读的文章。
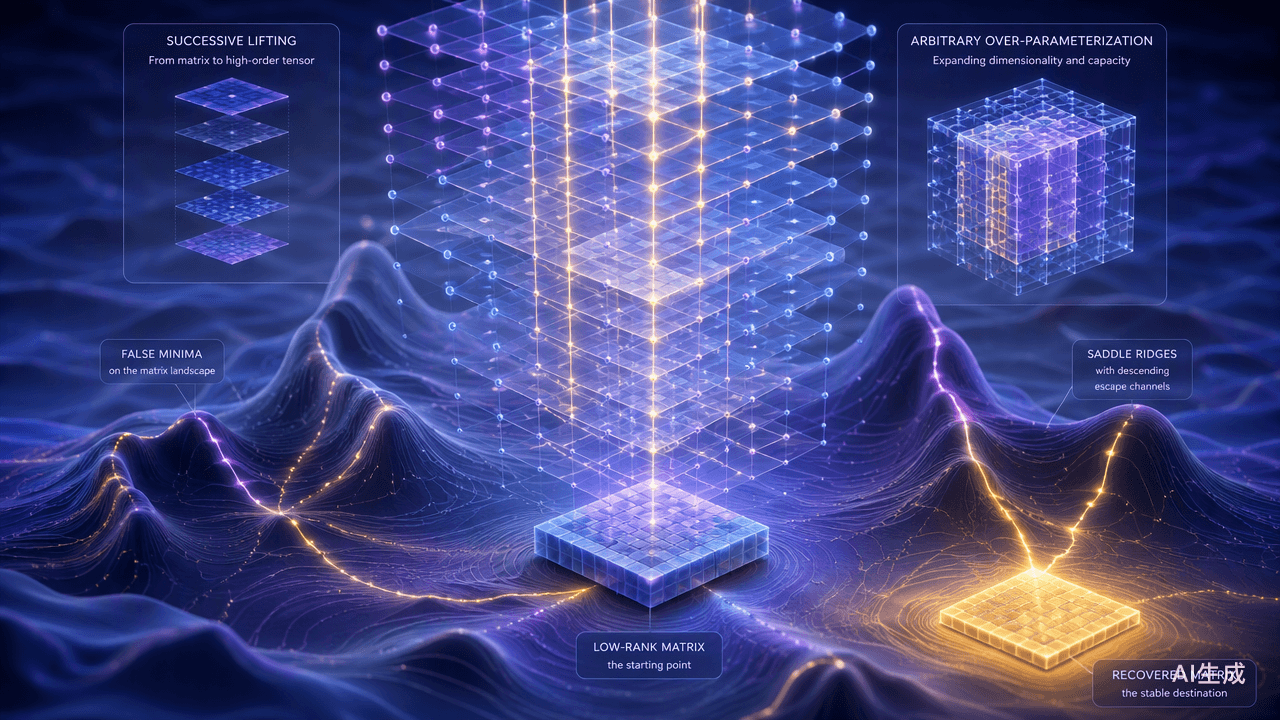
Over-parametrization via Lifting for Low-rank Matrix Sensing: Conversion of Spurious Solutions to Strict Saddle Points
This paper studies the role of over-parametrization in solving non-convex optimization problems. The focus is on the important class of low-rank matrix sensing, where we propose an infinite hierarchy of non-convex problems via the lifting technique and the Burer-Monteiro factorization. This contrasts with the existing over-parametrization technique where the search rank is limited by the dimension of the matrix and it does not allow a rich over-parametrization of an arbitrary degree. We show that although the spurious solutions of the problem remain stationary points through the hierarchy, they will be transformed into strict saddle points (under some technical conditions) and can be escaped via local search methods. This is the first result in the literature showing that over-parametrization creates a negative curvature for escaping spurious solutions. We also derive a bound on how much over-parametrization is requited to enable the elimination of spurious solutions.
Semidefinite Programming versus Burer-Monteiro Factorization for Matrix Sensing
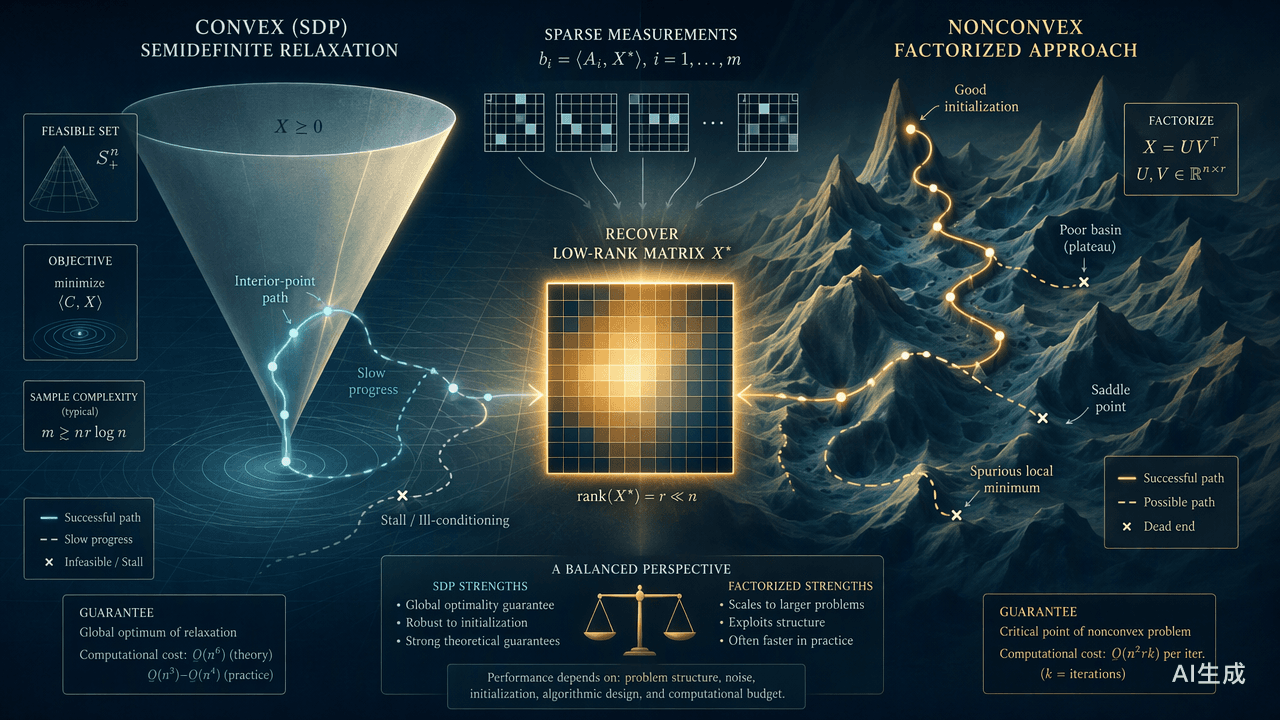
Many fundamental low-rank optimization problems, such as matrix completion, phase synchronization/retrieval, power system state estimation, and robust PCA, can be formulated as the matrix sensing problem. Two main approaches for solving matrix sensing are based on semidefinite programming (SDP) and Burer-Monteiro (B-M) factorization. The SDP method suffers from high computational and space complexities, whereas the B-M method may return a spurious solution due to the non-convexity of the problem. The existing theoretical guarantees for the success of these methods have led to similar conservative conditions, which may wrongly imply that these methods have comparable performances. In this paper, we shed light on some major differences between these two methods. First, we present a class of structured matrix completion problems for which the B-M methods fail with an overwhelming probability, while the SDP method works correctly. Second, we identify a class of highly sparse matrix completion problems for which the B-M method works and the SDP method fails. Third, we prove that although the B-M method exhibits the same performance independent of the rank of the unknown solution, the success of the SDP method is correlated to the rank of the solution and improves as the rank increases. Unlike the existing literature that has mainly focused on those instances of matrix sensing for which both SDP and B-M work, this paper offers the first result on the unique merit of each method over the alternative approach.
Algorithmic Regularization in Tensor Optimization: Towards a Lifted Approach in Matrix Sensing
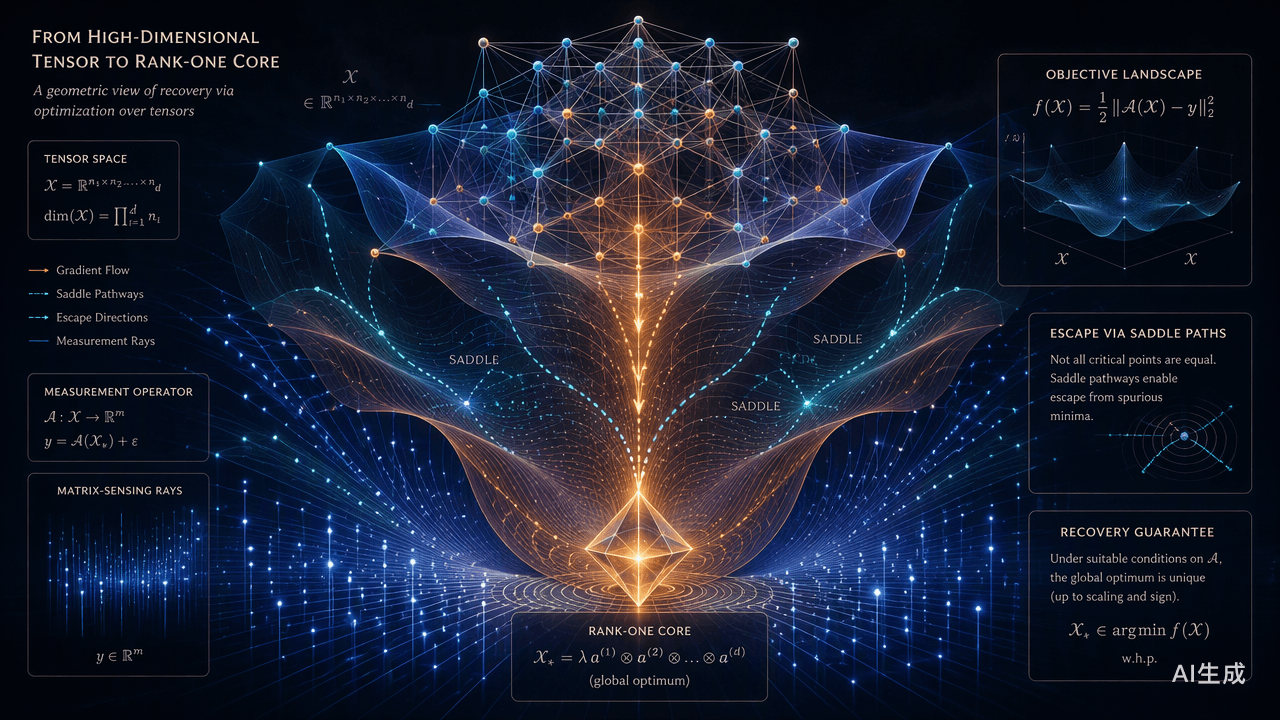
Gradient descent (GD) is crucial for generalization in machine learning models, as it induces implicit regularization, promoting compact representations. In this work, we examine the role of GD in inducing implicit regularization for tensor optimization, particularly within the context of the lifted matrix sensing framework. This framework has been recently proposed to address the non-convex matrix sensing problem by transforming spurious solutions into strict saddles when optimizing over symmetric, rank-1 tensors. We show that, with sufficiently small initialization scale, GD applied to this lifted problem results in approximate rank-1 tensors and critical points with escape directions. Our findings underscore the significance of the tensor parametrization of matrix sensing, in combination with first-order methods, in achieving global optimality in such problems.
Absence of spurious solutions far from ground truth: A low-rank analysis with high-order losses
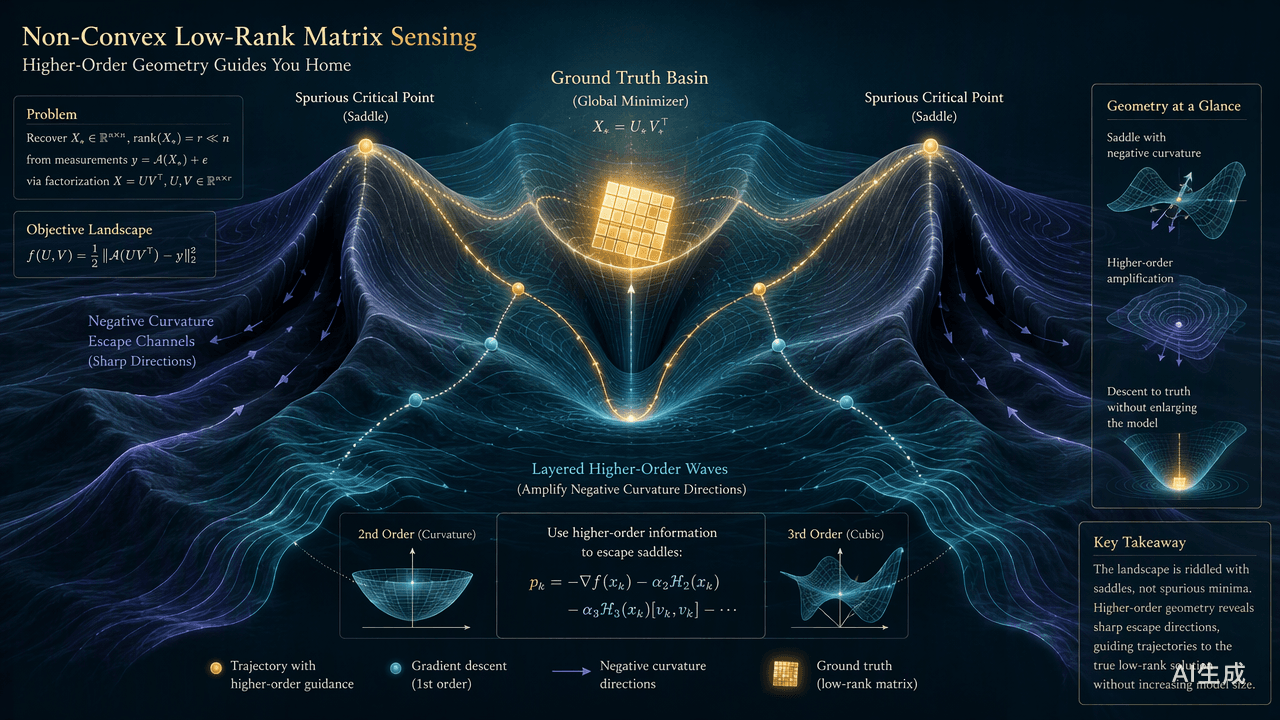
Matrix sensing problems exhibit pervasive non-convexity, plaguing optimization with a proliferation of suboptimal spurious solutions. Avoiding convergence to these critical points poses a major challenge. This work provides new theoretical insights that help demystify the intricacies of the non-convex landscape. In this work, we prove that under certain conditions, critical points sufficiently distant from the ground truth matrix exhibit favorable geometry by being strict saddle points rather than troublesome local minima. Moreover, we introduce the notion of higher-order losses for the matrix sensing problem and show that the incorporation of such losses into the objective function amplifies the negative curvature around those distant critical points. This implies that increasing the complexity of the objective function via high-order losses accelerates the escape from such critical points and acts as a desirable alternative to increasing the complexity of the optimization problem via over-parametrization. By elucidating key characteristics of the non-convex optimization landscape, this work makes progress towards a comprehensive framework for tackling broader machine learning objectives plagued by non-convexity.
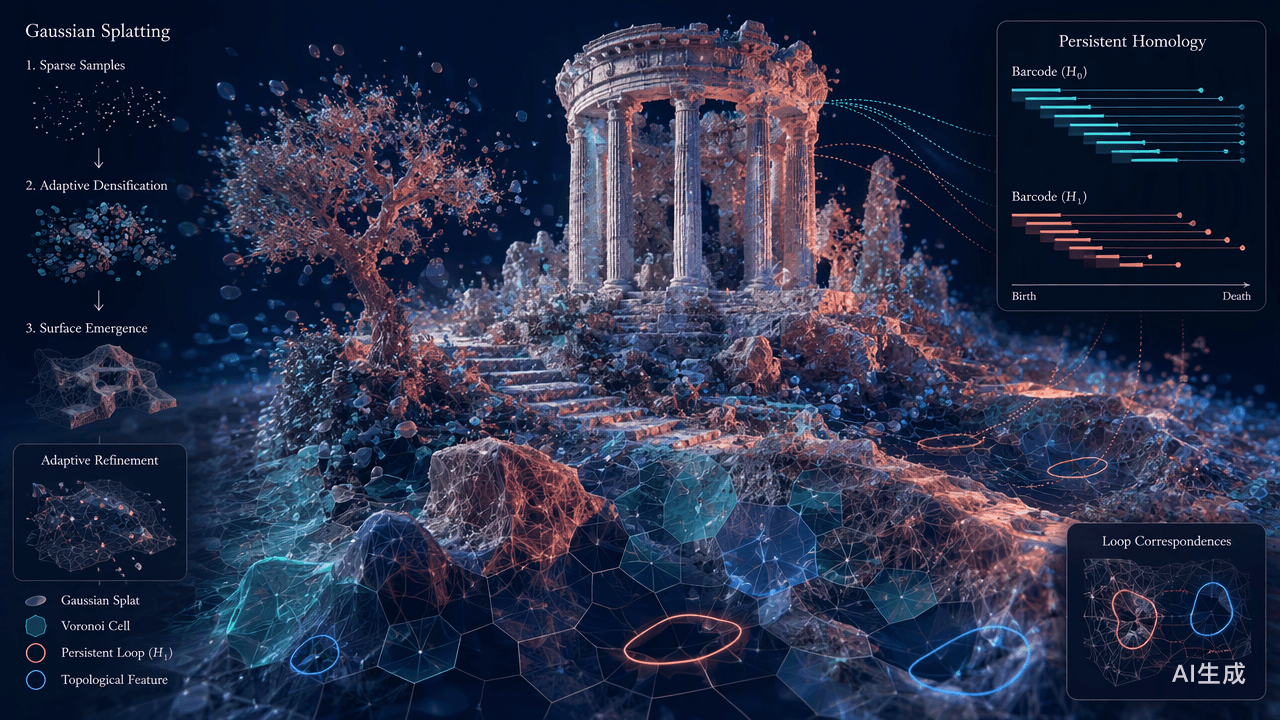
Topology-Aware 3D Gaussian Splatting: Leveraging Persistent Homology for Optimized Structural Integrity
Gaussian Splatting (GS) has emerged as a crucial technique for representing discrete volumetric radiance fields. It leverages unique parametrization to mitigate computational demands in scene optimization. This work introduces Topology-Aware 3D Gaussian Splatting (Topology-GS), which addresses two key limitations in current approaches: compromised pixel-level structural integrity due to incomplete initial geometric coverage, and inadequate feature-level integrity from insufficient topological constraints during optimization. To overcome these limitations, Topology-GS incorporates a novel interpolation strategy, Local Persistent Voronoi Interpolation (LPVI), and a topology-focused regularization term based on persistent barcodes, named PersLoss. LPVI utilizes persistent homology to guide adaptive interpolation, enhancing point coverage in low-curvature areas while preserving topological structure. PersLoss aligns the visual perceptual similarity of rendered images with ground truth by constraining distances between their topological features. Comprehensive experiments on three novel-view synthesis benchmarks demonstrate that Topology-GS outperforms existing methods in terms of PSNR, SSIM, and LPIPS metrics, while maintaining efficient memory usage. This study pioneers the integration of topology with 3D-GS, laying the groundwork for future research in this area.
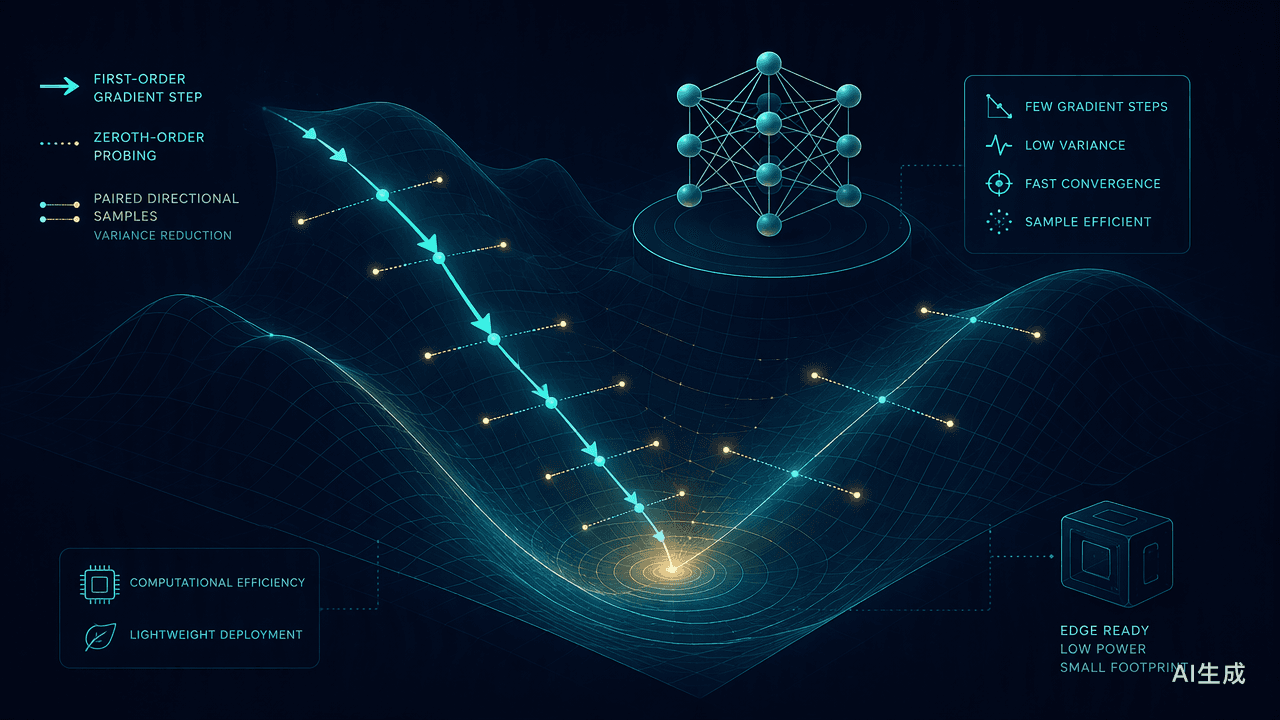
VAMO: Efficient Zeroth-Order Variance Reduction for SGD with Faster Convergence
Optimizing large-scale nonconvex problems, common in deep learning, demands balancing rapid convergence with computational efficiency. First-order (FO) optimizers, which serve as today’s baselines, provide fast convergence and good generalization but often incur high computation and memory costs due to the large size of modern models. Conversely, zeroth-order (ZO) algorithms reduce this burden using estimated gradients, yet their slow convergence in high-dimensional settings limits practicality. We introduce VAMO (VAriance-reduced Mixed-gradient Optimizer), a stochastic variance-reduced method that extends mini-batch SGD with full-batch ZO gradients under an SVRG-style framework. VAMO’s hybrid design utilizes a two-point ZO estimator to achieve a dimension-agnostic convergence rate of , where is the number of iterations and is the batch-size, surpassing the dimension-dependent slowdown of purely ZO methods and significantly improving over SGD’s rate. Additionally, we propose a multi-point variant that mitigates the error by adjusting the number of estimation points to balance convergence and cost. Importantly, VAMO achieves these gains with smaller dynamic memory requirements than many FO baselines, making it particularly attractive for edge deployment. Experiments including traditional neural network training and LLM finetuning confirm that VAMO not only outperforms established FO and ZO methods, but also does so with a light memory footprint.
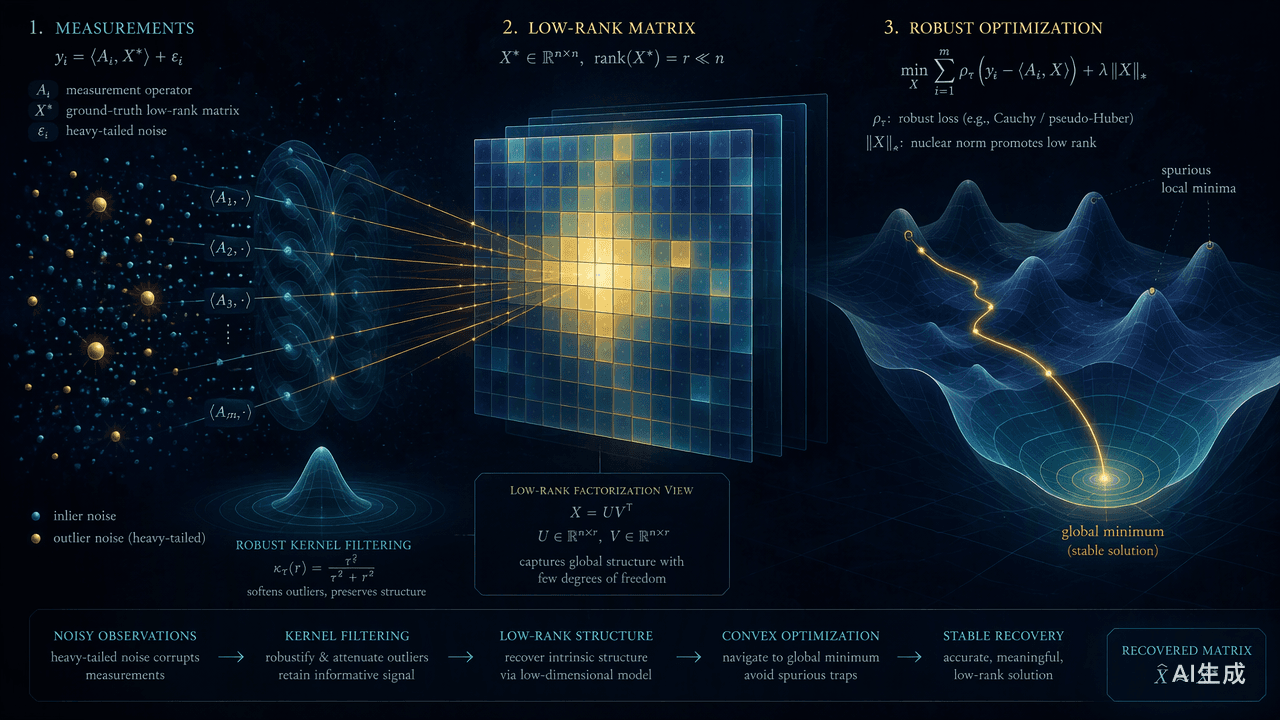
Matrix Sensing with Kernel Optimal Loss: Robustness and Optimization Landscape
In this paper we study how the choice of loss functions of non-convex optimization problems affects their robustness and optimization landscape, through the study of noisy matrix sensing. In traditional regression tasks, mean squared error (MSE) loss is a common choice, but it can be unreliable for non-Gaussian or heavy-tailed noise. To address this issue, we adopt a robust loss based on nonparametric regression, which uses a kernel-based estimate of the residual density and maximizes the estimated log-likelihood. This robust formulation coincides with the MSE loss under Gaussian errors but remains stable under more general settings. We further examine how this robust loss reshapes the optimization landscape by analyzing the upper-bound of restricted isometry property (RIP) constants for spurious local minima to disappear. Through theoretical and empirical analysis, we show that this new loss excels at handling large noise and remains robust across diverse noise distributions. This work offers initial insights into enhancing the robustness of machine learning tasks through simply changing the loss, guided by an intuitive and broadly applicable analytical framework.
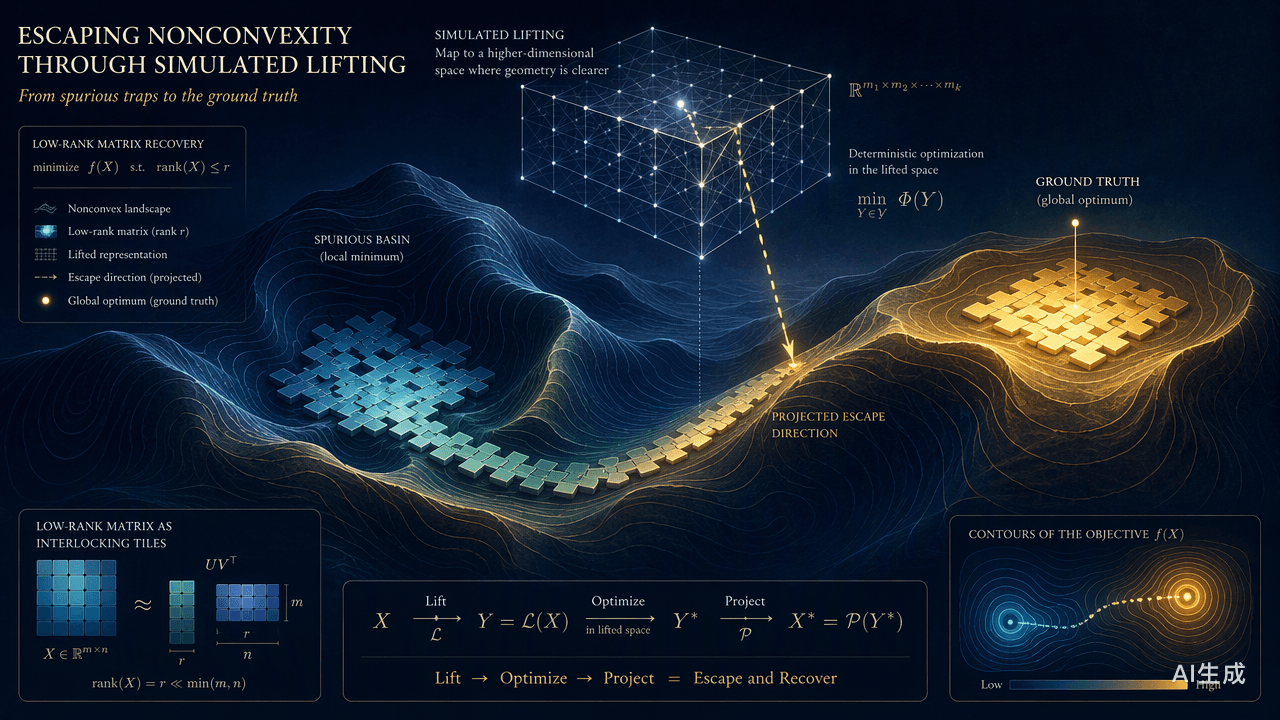
Escaping Local Minima Provably in Non-convex Matrix Sensing: A Deterministic Framework via Simulated Lifting
Low-rank matrix sensing is a fundamental yet challenging nonconvex problem whose optimization landscape typically contains numerous spurious local minima, making it difficult for gradient-based optimizers to converge to the global optimum. Recent work has shown that over-parameterization via tensor lifting can convert such local minima into strict saddle points, an insight that also partially explains why massive scaling can improve generalization and performance in modern machine learning. Motivated by this observation, we propose a Simulated Oracle Direction (SOD) escape mechanism that simulates the landscape and escape direction of the over-parametrized space, without resorting to actually lifting the problem, since that would be computationally intractable. In essence, we designed a mathematical framework to project over-parametrized escape directions onto the original parameter space to guarantee a strict decrease of objective value from existing local minima. To the best of our knowledge, this represents the first deterministic framework that could escape spurious local minima with guarantee, especially without using random perturbations or heuristic estimates. Numerical experiments demonstrate that our framework reliably escapes local minima and facilitates convergence to global optima, while incurring minimal computational cost when compared to explicit tensor over-parameterization. We believe this framework has non-trivial implications for nonconvex optimization beyond matrix sensing, by showcasing how simulated over-parameterization can be leveraged to tame challenging optimization landscapes.
平台推荐的学者及其代表作,方便你继续延伸阅读。
左右滑动查看更多作者